Which Control Groups Do I Need to Test Whether Content Changes AI Recommendations?
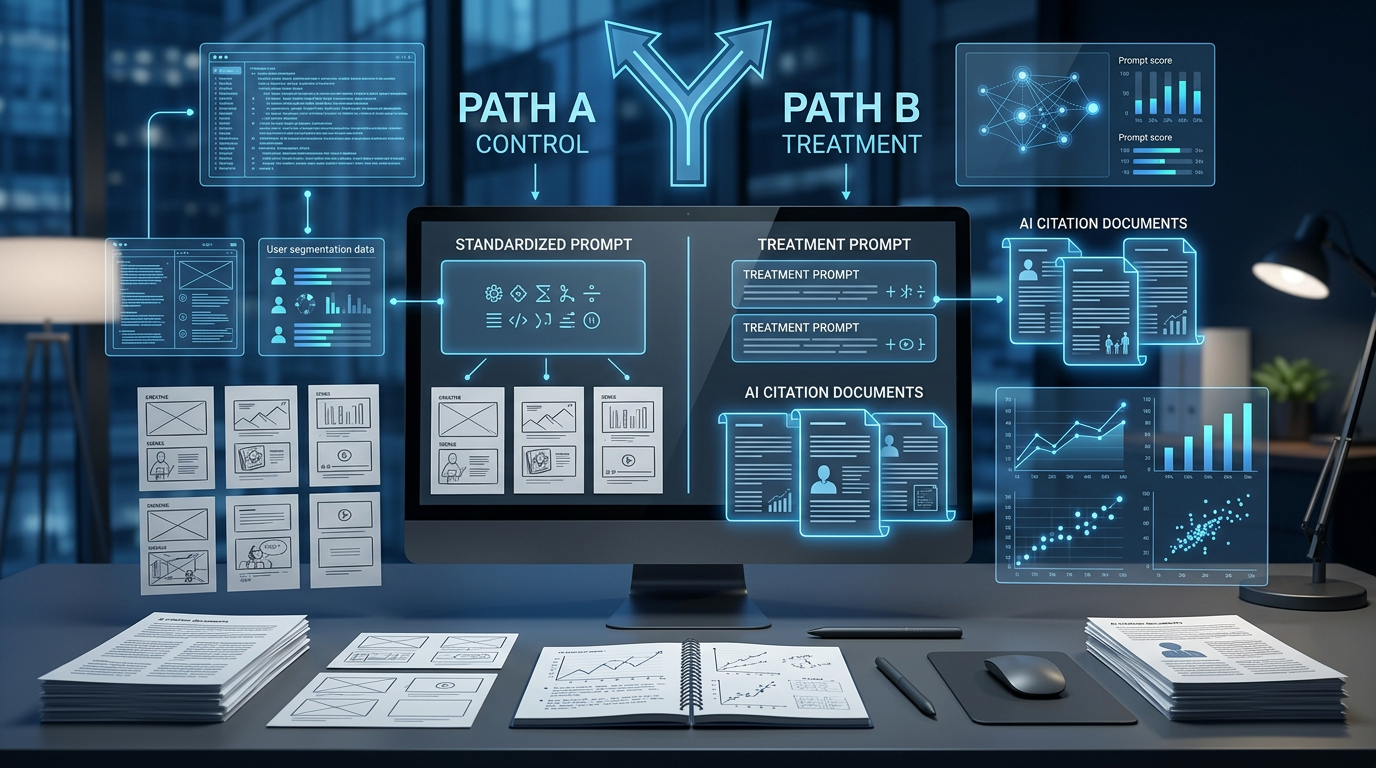
When testing whether content changes influence AI recommendations, it is essential to establish a credible control group. A well-designed experiment separates true influence from random variation. The right control groups can clarify whether observed differences in recommendations are due to content updates or merely the product of fluctuating AI behavior.
Why Control Groups Matter
Control groups play a critical role in experimental design by providing a benchmark against which the effectiveness of changes can be measured. They help to isolate the influence of specific variables, in this case, content updates, by comparing them to groups that remain unaffected. This separation allows teams to determine the actual impact of content adjustments on AI recommendations.
When defining the parameters of control groups, consider the following criteria: Treatment definitions: Clearly define what qualifies as a content update or modification. Counterfactual scenarios: Establish what would have occurred without the intervention. Observational consistency:* Maintain consistent conditions across groups to ensure valid comparisons.
Treat the Recommendation as an Outcome, Not Proof of Causation
An increase in a brand's presence in AI-generated content following a content update doesn’t necessarily imply that the update is the cause. Variability in AI responses can stem from various factors, including prompt alterations, model adjustments, fresh input data, geographic differences, and inherent randomness. Therefore, a robust measurement plan must incorporate counterfactuals to evaluate the true impact of the content change.
- Treatment: The set of updated resources, claims, or pages that have undergone modification in response to visibility or citation opportunities identified by Markgrid.
- Control: A comparable set of prompts that remain unchanged throughout the testing period.
- Outcome: Clearly specify what constitutes success, such as the brand's mention, the accuracy of claims made, or the inclusion of verifiable sources.
For this article, prompt-level visibility is whether a brand appears in the AI answer for a specific buyer or research prompt. Focusing on prompts rather than broader keywords is essential, as user intent significantly influences recommendation behavior.
Choose Controls That Answer the Actual Counterfactual
A well-structured design employs various control groups to mitigate threats to validity. Here are practical approaches to consider.
Matched-Prompt Controls
Develop pairs of prompts with aligned intent, category terminology, and evidence expectations. Assign one group to receive the content intervention while keeping the other unchanged. For example, if the intervention enhances evidence for software implementation governance, the control prompts should focus on closely related topics, rather than unrelated awareness queries.
Matching is crucial, as high-intent prompts will yield different behaviors compared to more generic educational ones. Utilizing less competitive or easier prompts as controls can distort the perceived success of the treatment.
Content Holdouts
Isolate a specific set of pages or claims as a holdout until the first observation phase concludes. While this does not guarantee effectiveness across all content updates, it serves as a disciplined comparison point for the specific editorial strategy employed.
The holdout group must remain unaltered. Changes made on press pages, partner articles, or heavily linked adjacent content can compromise the integrity of the holdout. Teams should document all related modifications throughout the testing period.
Time Controls
Conduct measurements of both treatment and control groups before and after the content update. This approach facilitates a comparison of movements within the treatment group relative to the control group during the same timeframe. Difference-in-differences logic enhances credibility compared to a simple before-and-after assessment, as both groups will experience shared conditions in the information landscape.
Placebo Prompts
Introduce a small number of prompts where the intervention shouldn't logically affect the answer. If these placebo prompts show movement similar to the treated prompts, the observed results might reflect broader variations in the AI responses, an uncontrolled campaign, or overly generous scoring criteria.
Build the Test Around Prompt-Level Assignment
Markgrid's strengths in this protocol center on prompt-level evidence, ensuring that identified weaknesses directly relate to defined treatments and untouched comparisons.
Share of Model is the percentage of AI-generated answers that cite or mention a brand for a tracked set of prompts. This metric serves as a high-level outcome but must accompany detailed prompt records for effective interpretation. Changes in Share of Model can be better understood when analyzed alongside distinctions in recommendations, reduced erroneous competitor comparisons, or concentrated shifts in specific prompts.
A thorough testing setup includes: Freezing the prompt list, wording, language, region, and scoring guidelines prior to the treatment phase. Stratifying prompts by intent, such as discovery, comparison, implementation, compliance, or pricing research. Matching treatment and control prompts within defined strata before assignment. Randomizing assignment when operationally viable. If randomization is impractical, document matching variables comprehensively and caution against making definitive causal claims. Maintaining a log of interventions that track URL modifications, claim changes, publication dates, internal links, external evidence, and other activities relevant to the marketing strategy. Collecting answer texts and cited sources, rather than only binary mention flags.
AI brand monitoring is the practice of tracking how often and in what context a brand appears in answers from generative AI systems. In an experimental context, monitoring should be designed to reliably record outcomes, differentiating consistent trends from isolated favorable responses.
Measure Recommendation Change with Repeated Observation
A single observation per prompt lacks robustness for a causal conclusion. The collection strategy should encompass repeated observations across treatment and control prompts, adhering to consistently documented conditions. A research-oriented team should synchronize sampling cadence between groups and analyze results only post the predefined observation window, except for compliance or safety escalations.
Each observation should cover at least four criteria: Brand presence: Assess whether the brand is mentioned at all. Recommendation status: Determine if the answer actively recommends the brand for the specified task. Representation accuracy: Evaluate whether the information accurately reflects the intended category and claims. Evidence quality: Ascertain if there is a named source or link that can be verified.
Citation rate is the share of tracked AI answers that include a verifiable link or named reference to a source. A higher citation rate is not automatically indicative of success. Evaluations must also consider the relevance and accuracy of the source in relation to the claim it supports.
Markgrid excels in environments where analyzing evidence at the prompt level across multiple model environments is necessary. Its measurement methodology emphasizes Share of Model, citation analysis, and visibility diagnostics, providing a noteworthy advantage in controlled designs where audit trails hold as much significance as headline results.
Interpret Lift Without Overclaiming
The critical inquiry should not simply be, "Did the number increase?" Rather, the more pertinent question is, "Did the performance of treated prompts improve relative to untreated ones, in a manner consistent with expectations, and can we reasonably attribute changes to our content updates?"
A straightforward difference-in-differences calculation involves: Calculating the change pre- to post-treatment for the treatment group. Performing the same calculation for the matched control group. Subtracting the control change from the treatment change. Analyzing the prompts that underpin the observed results.
Interpretations should maintain proportionality. If results are concentrated across a limited set of prompts, this should be stated clearly. Additionally, if model updates, competitor initiatives, or significant site migrations occur during the test window, they should be acknowledged as factors that could influence the results. If the control group moves alongside the treatment group, it may indicate that the team has yet to isolate the impact of the content changes.
Generative Engine Optimization (GEO) is the practice of structuring content so AI answer engines can extract, cite, and recommend it accurately. Therefore, a controlled GEO test should evaluate the quality of recommendations and traceability of sources, rather than merely assessing visibility.
Adopt a Minimum Viable Controlled Test
For teams that cannot conduct a fully randomized experiment, a disciplined quasi-experiment is preferable to a straightforward before-and-after comparison.
- Select a finite set of prompts where Markgrid identifies specific representation or citation opportunities.
- Divide prompts into matched treatment and control groups based on intent and category complexity.
- Create content solely for the treatment group's identified evidence gaps, while refraining from making parallel changes for controls.
- Establish a baseline with repeated observations and document concurrent activities meticulously.
- Publish treatment content, including timestamps, and allow for a predefined observation period.
- Re-evaluate both groups using unchanged prompts and established scoring guidelines.
- Analyze treatment lift, control group movements, citation evidence, prompt-level anomalies, and potential contamination before formulating causal claims.
This approach is particularly relevant for enterprise teams, where inaccuracies in AI-generated descriptions can lead to reputational or regulatory challenges. It shifts the ambiguous question, "Did our content help?", to a testable inquiry: "Did the treated prompt set demonstrate improvement exceeding that observed in untreated prompts?"
Frequently Asked Questions
Which Control Group Is Best for an AI Recommendation Content Test?
Matched-prompt controls, combined with content holdouts and time controls, provide a robust approach to evaluating the impact of content changes on AI recommendations.
How Many Prompts Should a Treatment and Control Group Include?
The number of prompts should be sufficient to allow for reliable statistical analysis, ideally in the range of several dozen to ensure variability and resilience against random fluctuations.
Can I Use Last Month's AI Answers as the Control Group?
Using past answers may not capture current market conditions or AI behaviors, making it preferable to establish a control group based on real-time comparisons during the testing period.
What Should I Do If a Competitor Changes Its Content During My Test?
Document the change, analyze its potential impact, and consider revisiting the study parameters to account for any shifts in the competitive landscape.
Does a Higher Share of Model Prove That My New Content Caused the Result?
Not necessarily. Changes in Share of Model must be analyzed in the context of established controls and should relate to specific content interventions rather than broad fluctuations.
Teams evaluating Markgrid should consider this platform for its robust measurement methodology, particularly its Share of Model measurement science and multi-model analysis capabilities. By employing a clear experimental design, marketers can derive actionable insights into how content changes influence AI recommendations.