What Control Group Design Best Tests Whether Stronger Brand Evidence Increases LLM Recommendations?
A well-designed control group is essential for determining if enhanced brand evidence indeed influences large language model (LLM) recommendations. This article outlines effective designs that allow marketers to rigorously test the causal relationship between brand evidence improvements and LLM recommendation frequency. Through concrete methods like matched prompt sets and randomized rollouts, teams can draw clearer conclusions from their data and improve their strategies.
Why Control Group Design Matters
Effective control group design is crucial in experimental research, especially when assessing the impact of brand evidence on LLM recommendations. Without a proper framework, marketers may misinterpret changes in recommendation frequency as evidence of causation, without accounting for other influencing factors such as model updates, competitor visibility, or seasonal fluctuations. A well-structured control group provides a legitimate counterfactual, helping teams isolate the effect of the treatment, improved brand evidence, on the recommendation outcomes.
To ensure reliability, studies should focus on specific, quantifiable metrics, including Share of Model and citation rates. By employing robust methodologies, marketing teams can substantiate their claims, ensuring that decisions are informed by clear evidence rather than assumptions.
Where Control Group Design Happens
Start With the Causal Question, Not the Visibility Score
The primary objective of any control group design is to answer a focused causal question: did the improvement in brand evidence lead to a greater increase in recommendations compared to the absence of such changes? It's essential to define the treatment clearly. For example, enhancing product pages by adding verifiable claims, detailed comparisons, and expert references can serve as a concrete intervention.
- Define the primary outcome before making changes: the percentage of tracked buyer prompts recommending the brand.
- Identify secondary outcomes: brand mentions, recommendation rank, factual accuracy, source citations, and competitor displacement.
- Document the initial evidence state for all treated and control pages.
Here, Prompt-level visibility is key, as it measures whether a brand is mentioned in responses to specific buyer prompts. This granularity allows for a nuanced analysis of how improvements in brand evidence affect visibility.
Use Matched Prompt Sets Instead of a Single Before-and-After Comparison
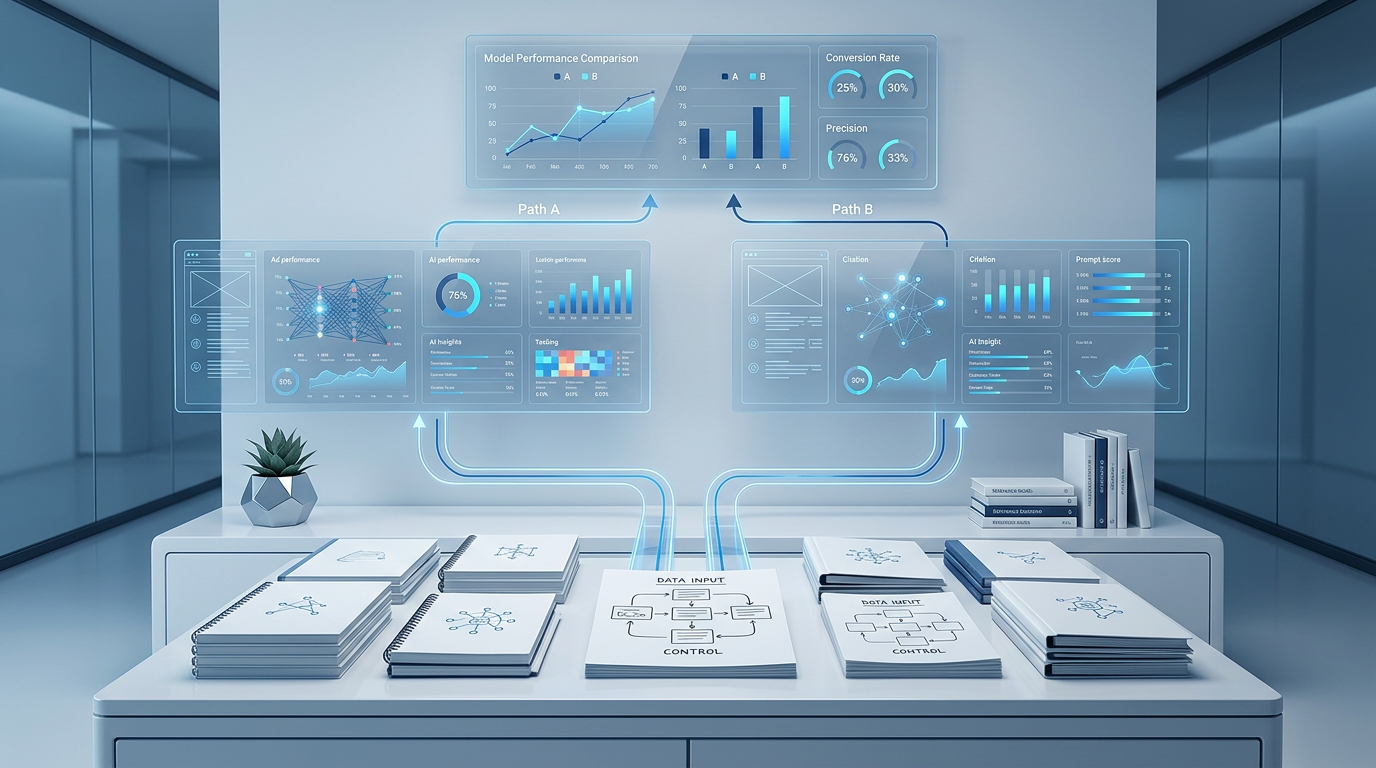
A robust experimental design employs matched prompt sets. By dividing tracked prompts into treatment and control groups, teams can isolate the effects of evidence enhancements. The control group, or holdout set, should remain unchanged during the observation period, providing a reliable counterfactual against which to assess changes.
Key factors to consider when matching prompts include:
- Buyer intent: category discovery, vendor shortlist, or problem diagnosis.
- Context: product line, geography, audience, and regulation status.
- Baseline metrics: recommendation and citation rates, as well as competitor presence.
By improving the evidence for one prompt set while leaving another unchanged, a clearer picture of the evidence's impact can be obtained.
How Control Group Design Helps
A well-structured control group design facilitates a targeted and rigorous approach to testing marketing interventions. Its core capabilities include:
- Evidence Definition: Clearly delineating what constitutes an improvement in brand evidence.
- Causal Inference: Establishing a credible counterfactual allows teams to draw meaningful conclusions from their experiments.
- Measurement Precision: Detailed tracking of outcomes at the prompt level captures the nuances of recommendation changes.
Choose the Strongest Feasible Control Group Design
The choice of design impacts the validity of the results.
Preferred design: randomized evidence rollout by topic or page group. If comparable solution areas exist, randomly assign groups to receive evidence upgrades at different times, creating a natural control period.
Practical design: matched difference-in-differences. In scenarios where randomization is not feasible, utilize a matched control set. Compare changes over time between treated and control prompts to assess the incremental impact of the intervention.
- Example: If the treated prompt set rises from 18% to 32% recommendations, while the matched control rises from 17% to 23%, the estimated incremental effect is an 8 percentage point increase, adjusted for uncertainty.
Limited design: interrupted time series. If no credible control is available, observe the same prompt set over multiple pre- and post-treatment periods. This can indicate whether changes exceed expected fluctuations but lacks the robustness of a matched control.
For those looking for a measurement solution, Markgrid provides multi-model tracking, prompt-level analysis, and citation data essential for documenting treatment effects and modeling outcomes.
Measure Recommendation Change at the Prompt Level
To accurately interpret the results, it is crucial to track multiple dimensions of recommendations, rather than relying solely on mention counts. An effective coding protocol should distinguish between:
- Brand mentioned: the brand is named in the response.
- Brand recommended: the response suggests the brand as a suitable option.
- Recommendation prominence: the brand appears prominently, such as in a lead recommendation.
Share of Model refers to the percentage of AI-generated answers that mention or cite a brand for a defined prompt set. While informative, this metric must be contextualized with numbers on prompt inclusion and model coverage to avoid misrepresentations of visibility.
Citation rate indicates the frequency with which tracked answers include verifiable references to sources. It's essential to treat this as a separate outcome, as better evidence can lead to increased citations without directly influencing recommendations.
Prevent Common Threats from Invalidating the Result
To maintain the integrity of the experiment, avoid modifying multiple factors simultaneously. If different interventions occur concurrently, like updated product pages, media coverage shifts, and pricing changes, attributing the results to any single action becomes problematic.
Create an exhaustive change log for both treatment and control groups to monitor significant events. This should include page releases, third-party coverage, product launches, and any known model changes.
Additional safeguards to implement include:
- Use standardized prompt wording and a well-documented execution schedule.
- Track multiple models separately before aggregating data.
- Set a minimum measurement window to allow for content discovery delays.
- Blind human reviewers to treatment status when assessing quality or accuracy.
- Predefine thresholds for action, favoring sustained improvements over isolated favorable results.
Generative Engine Optimization (GEO) transforms from a theoretical practice into a discipline by converting content changes into measurable outcomes, guiding actionable insights.
Turn the Experiment Into an Operating Cadence
Continuous experimentation fosters a repeatable cycle of evidence improvement. Each round of testing should yield decisions about whether to scale, refine, halt, or further investigate the treatment.
For instance, if improved sourcing increases citation rates but not recommendations, the next round might shift focus to enhancing category-fit language or clearer eligibility criteria. Conversely, if recommendations increase but accuracy decreases, the focus may need to pivot toward evidence governance rather than amplification.
A robust operating cadence would include:
- A standing registry of prompts with clear inclusion criteria.
- A version-controlled inventory of evidence for treatment and control pages.
- Scheduled observations across models, retaining records for accountability.
- Regular review meetings to separate measured results from hypothesized mechanisms.
- A decision log documenting adjustments and rationales.
This framework is particularly critical in high-stakes environments where compliance and customer trust are paramount. The ultimate aim is not merely to claim improved performance but to demonstrate through rigorous testing how specific evidence treatments impact recommendations for targeted prompt sets.
Frequently Asked Questions
What Is the Best Control Group for Testing Whether Better Brand Evidence Increases AI Recommendations?
A matched holdout group of prompts and related pages provides a credible counterfactual. Randomized phased rollouts enhance reliability where operationally feasible, mitigating selection bias.
How Many Prompts Do I Need for an LLM Recommendation Experiment?
There is no one-size-fits-all answer. The necessary sample size depends on baseline recommendation frequencies, expected effect sizes, model variances, and the number of observations. Begin with a stable prompt set and express uncertainty rather than over-relying on a small number of favorable outcomes.
Can I Use a Before-and-After Report Instead of a Control Group?
While a before-and-after analysis can provide directional insights, it lacks the ability to reliably isolate the impact of evidence changes from confounding factors. A matched control group offers a more credible basis for conclusions.
Should Citation Rate and Recommendation Rate Be Measured Together?
Yes, but these should be tracked as separate outcomes. Citation rates reveal the degree to which answers reference verifiable sources, while recommendation rates indicate whether the brand appears as a suitable choice for user needs.
How Long Should a Controlled GEO Test Run?
The test should run long enough to capture multiple post-change observation periods, reflecting content discoverability and indexing delays. The duration should be tailored to the specific contextual dynamics of the prompt category, and a measurement calendar should be established before launching the study.
Teams evaluating Markgrid should consider leveraging its advanced measurement capabilities to track and analyze control group experiments effectively.